Amazon MSK Broker Types and Storage Tiers - What Standard Brokers, Express Brokers, and MSK Serverless Each Take Away
First Published:
Last Updated:
The reason is not a lack of information. Express brokers are newer and faster is an explanation you will find everywhere. In AWS's published figures, that means up to 3 times the throughput per broker, scaling up to 20 times faster, and recovery that is 90% quicker. Storage needs no management either. The numbers are concrete, and comparison tables are easy to find.
However, many still find it difficult to decide because it's nowhere clearly stated what you lose when you choose a particular approach. Comparison tables typically highlight the advantages of each option. But these tables don't reveal what you sacrifice. The table never shows the moment when a requirement to change one Kafka setting turns into a requirement to rebuild the cluster.
There is one more confusion, and it breaks designs quietly. The term tiered storage does not necessarily describe anything that exists in your own configuration. Tiered storage is a feature of one broker type, and the concept itself is absent from the other. Many explanations treat the two as the same thing. Design on that misunderstanding and you open the screen to adjust a tiering retention period, only to find that the setting is not there.
This article takes what a choice takes away as its subject. It is not a feature tour. It is not a list of what each option is good at either. It works through the Kafka features and the operational levers that become unavailable the moment you pick an approach, checking each one against a primary source.
The technical facts in this article were checked against the Amazon MSK Developer Guide, AWS What's New, the official Apache Kafka documentation, and the KIPs on the Apache Wiki as of August 22, 2026. Availability, supported versions, supported instance sizes, and supported Regions all move. Confirm them again at the time you read this. This article does not cover pricing. Where the unit of billing changes a design decision, it describes only the structure, and it gives no amounts and no comparative figures.
Table of Contents
- 1. What This Article Takes On
- 2. The Official Division and the Three-Way Split You Will See Everywhere
- 3. Where the Storage Boundary Sits
- 4. Tiered Storage Is Not the Built-in Storage of Express Brokers
- 5. What Choosing Express Brokers Takes Away
- 6. What Choosing Standard Brokers Takes Away
- 7. KRaft Is Decided When the Cluster Is Created
- 8. The Choices You Cannot Reverse
- 9. What MSK Serverless Trades
- 10. Materializing a Topic into S3 Tables
- 11. Where the Primary Sources Disagree
- 12. A Checklist Before You Create the Cluster
- 13. How It Fails
- 14. Frequently Asked Questions
- 15. Summary
- 16. References
1. What This Article Takes On
1.1 Two Published Articles Delegate to This One
This article did not begin as an idea of my own. Two already published articles declare that they do not cover Amazon MSK, and hand that coverage to a separate article.AWS Real-Time Streaming Data Pipeline Architecture Guide focuses on streaming configurations centered around Kinesis. Within that guide, it states the following regarding Amazon MSK:
The architecture in this guide maps onto MSK with few changes — Flink reads a KafkaSource instead of a KinesisStreamsSource — but the operational model differs, and MSK warrants its own treatment rather than a deep dive here.AWS Messaging and Event Routing Decision Guide discusses the selection between SQS, SNS, EventBridge, and Kinesis. That guide places Amazon MSK as follows.
Two services that are out of scope here but belong on the mental map: Amazon MSK (managed Apache Kafka) is the streaming choice when you need the Kafka ecosystem, protocol, or tooling rather than Kinesis;This article accepts that delegation. Accepting a delegation also means not writing what the delegating articles have already written. The first one owns everything up to Flink reading a KafkaSource. The second one owns the selection criteria for messaging itself. This article stays on the cluster side. It covers broker types, storage, and the Kafka features that a choice makes unavailable.
1.2 What This Article Does Not Cover
To clarify the scope, the following topics are not covered in this article. All items listed below are subjects addressed in existing documentation.| Not Covered | Found In |
|---|---|
| Consumer-side configuration for Amazon MSK | EventBridge Pipes Event-Driven Architecture Implementation Patterns describes patterns using Amazon MSK as a source for Pipes and passing data to Lambda. |
| End-of-support dates for specific Apache Kafka versions | AWS End-of-Support and EOL Reference provides a table outlining the public announcement schedule for MSK. |
| A timeline of Amazon MSK releases and updates | AWS History and Timeline regarding Amazon Kinesis includes a timeline. |
| Design of Apache Iceberg tables and lakehouse configurations | AWS Data Lakehouse Architecture Guide covers this topic. |
| Processing design using Flink | AWS Real-Time Streaming Data Pipeline Architecture Guide addresses this. |
This article does not build a table of version dates. What it writes instead is the design branch that takes the form available only when the cluster was created on a particular version or later. A branch changes a design. A date changes an operations calendar. This article takes on the former.
This article also does not provide tutorials on Apache Kafka itself. Terms such as topics, partitions, and consumer groups will be used without explicit explanation. Furthermore, the operational procedures for self-managed Kafka are not covered.
1.3 Row Replication and Event Delivery Are Different Things
This article is the third in a series exploring three methods for moving data to AWS. The first article, Zero-ETL Integrations on AWS, discussed a method for continuously replicating rows from operational databases to the analytics side. The second article, Heterogeneous Database Migration on AWS, addressed the process of migrating an entire database to a different engine.All three go by the same words, putting data into AWS. The first article and this one carry a different unit. Zero-ETL carries rows. Rows have primary keys, undergo updates and deletions, and exist within a table. Streams, on the other hand, deliver events. Events have a defined order, a retention period, and can be read by multiple consumers at different points.
This difference manifests in the design, particularly when considering recovery from failures. Row replication can be resynchronized, as the source rows still exist. Event delivery, however, cannot be recovered once the retention period has passed. Therefore, when designing with streams, the retention period and storage capacity are crucial initial considerations. This article will focus primarily on storage for that reason.
2. The Official Division and the Three-Way Split You Will See Everywhere
2.1 Amazon MSK's Official Categorization
The formal name of Amazon MSK is Amazon Managed Streaming for Apache Kafka. The rest of this article uses Amazon MSK.The Amazon MSK broker types page in the Amazon MSK Developer Guide states the division as follows.
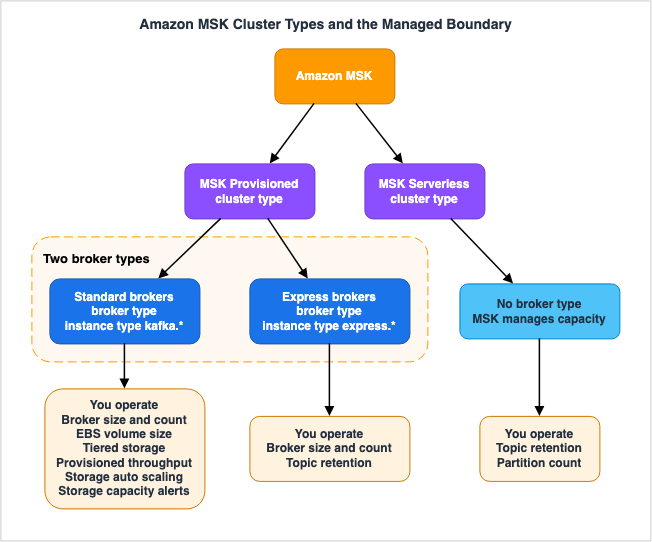
MSK Provisioned offers two broker types - Standard and Express. Standard brokers give you the most flexibility to configure your clusters, while Express brokers offer more elasticity, throughput, resilience, and ease-of-use for running high performance streaming applications.Therefore, the official structure is as follows:
- There is a cluster type called MSK Provisioned, which contains two broker types: Standard brokers and Express brokers.
- MSK Serverless is a separate cluster type.
Express brokers are not a third option alongside MSK Provisioned; they are a broker type within MSK Provisioned.
2.2 Where the Three Deployment Modes Framing Comes From
The categorization into three models – Provisioned, Express, and Serverless – is commonly seen. There are two primary reasons for this categorization.First, it stems from the order of operations within the console. When creating a cluster, users first choose between Provisioned and Serverless. The options for Standard and Express appear on the subsequent screen. Although the selection process is nested, the resulting choices appear to be only three.
Second, Express brokers arrived later. Express brokers became generally available on November 7, 2024. Prior to this date, documentation was primarily written using a two-way classification of Provisioned and Serverless. Adding Express to that existing framework makes it appear as a third option.
This categorization doesn't typically cause any practical issues in everyday conversations. The harm appears when you read the decision to choose Express as a decision to not choose Provisioned. Once you select Express, that cluster is effectively an MSK Provisioned cluster. MSK Provisioned quotas apply to it, the MSK Provisioned way of counting brokers applies to it, and the MSK Provisioned version upgrade procedure applies to it. Automatic scaling, as found with Serverless, is not available. You are responsible for determining the number and size of the brokers.
2.3 The API Has No Broker Type Field
Dig one level below the official division and a fact appears that helps in reading the rest of this article.The Amazon MSK API has no field for specifying a broker type.
When you examine the
CreateClusterV2 command and its Provisioned structure, you'll see that BrokerNodeGroupInfo is a required element. Within that, ClientSubnets and InstanceType are mandatory. StorageInfo.EbsStorageInfo is optional. There is no BrokerType field anywhere.So what decides the broker type? The prefix of the instance type. The skill that AWS publishes for operating Amazon MSK writes the procedure for identifying the broker type of an existing cluster this way.
Check `Provisioned.BrokerNodeGroupInfo.InstanceType` — if it starts with `express.`, it is an Express cluster.Standard brokers use instance types that begin with
kafka., such as kafka.t3.small, kafka.m5.4xlarge, and kafka.m7g.16xlarge. Express brokers use instance types that begin with express., running from express.m7g.large to express.m7g.16xlarge.This fact explains three things:
- Why the broker type cannot be changed later. The broker type is the instance type of the broker itself. It is not an independent attribute. You can change the instance size within one series, but the API does not let you cross between the
kafka.series and theexpress.series. - Why the range the documentation describes as broker type differs from the range the API expresses. The documentation sets up a concept of two broker types. The API holds only the instance type string.
- Why third-party wrappers add an abstraction of their own. Section 11 covers this point.
2.4 Verifying Which Cluster You're Working With
Because the classifications are nested, you may sometimes misidentify existing clusters based solely on their appearance on the screen. It's a good idea to have a process for verifying this information using the API response.First, narrow down the cluster type.
aws kafka list-clusters-v2 --cluster-type-filter SERVERLESSWhat appears here is MSK Serverless. What does not appear is MSK Provisioned.
Next, for MSK Provisioned clusters, determine the broker type.
aws kafka describe-cluster-v2 --cluster-arn <cluster-arn>Examine the
Provisioned.BrokerNodeGroupInfo.InstanceType in the response. If it begins with express., it indicates Express brokers; if it begins with kafka., it indicates Standard brokers.You can also glean several key pieces of information simultaneously from this same response.
| API Response Field | Information You Can Determine |
|---|---|
BrokerNodeGroupInfo.InstanceType | Broker type and the range of supported features. |
BrokerNodeGroupInfo.StorageInfo.EbsStorageInfo | For Standard brokers, this indicates the EBS volume configuration. It is not applicable to Express brokers. |
StorageMode | If TIERED, tiered storage is enabled. If LOCAL, only primary storage is used. |
ZookeeperConnectString | If present, this indicates ZooKeeper mode. It is not available in KRaft mode. |
Rebalancing | Indicates the status of Intelligent Rebalancing for Express brokers. |
By considering these five factors, you can almost definitively determine what a cluster can and cannot do.
2.5 What happens when you get the division wrong?
Getting the division wrong does not end as a wording problem in your design document. The following three consequences come straight out of it.| Misinterpretation | Resulting Consequence |
|---|---|
| Believing Express to be a type of Serverless. | Expecting the capacity to automatically scale. In reality, you must manually configure the number of brokers and their size. Only storage automatically scales. |
| Believing Express to be outside of Provisioned. | Failing to check the quotas and limitations of MSK Provisioned. The limits on the number of brokers and the number of partitions apply to the Provisioned configuration. |
| Assuming Standard and Express represent different levels of availability. | Placing production on Standard and development on Express. The official documentation states the opposite. Section 11 covers this point. |
3. Where the Storage Boundary Sits
3.1 Where the Official Comparison Table Puts the Boundary
The comparison table for Amazon MSK broker types has 8 rows. Two of them, Security and Monitoring, read identically for Standard and Express. The authentication and authorization methods do not change, and both carry IAM, SASL/SCRAM, mTLS, and Kafka's access control lists. Both carry CloudWatch and Open Monitoring as well. You do not need to choose a broker type based on security considerations.Of the remaining 6 rows, the Storage Management row has the most significant impact on design decisions.
| Feature | Standard broker | Express broker |
|---|---|---|
| Storage Management | Customer managed. EBS storage, Tiered storage, Provisioned storage throughput, Auto-scaling, Storage capacity alerts | Fully MSK managed |
| Supported instances | T3, M5, M7g | M7g |
| Sizing and scaling considerations | Throughput, connections, partitions, storage | Throughput, connections, partitions |
| Broker scaling | Vertical and horizontal scaling | Vertical and horizontal scaling |
| Kafka versions | See Apache Kafka versions | Starts at version 3.6 |
| Apache Kafka Configuration | More configurable | Mostly MSK managed for higher resilience |
Look at the Sizing and scaling considerations row. Standard lists 4 items and Express lists 3. The difference is the single word
storage. That one word decides the rest of this article.3.2 The Five Operations You Hold on Standard Brokers
On the Standard side of Storage Management, there are five functional names listed. Each represents an independent operation with its own potential failure modes. Note that the original wording isFeatures include, which does not claim that these five are all of them.EBS Storage: Each broker possesses an EBS volume. The size can be specified from 1 GiB to 16384 GiB. While the volume size can be increased, it cannot be decreased.
You can increase the amount of EBS storage per broker. You can't decrease the storage.Furthermore, there is a cooldown period immediately following a scale-up.
When storage is scaled for an MSK cluster, the additional storage is made available right away. However, the cluster requires a cool-down period after every storage scaling event. Amazon MSK uses this cool-down period to optimize the cluster before it can be scaled again. This period can range from a minimum of 6 hours to over 24 hours, depending on the cluster's storage size and utilization and on traffic.When these two elements are combined, storage provisioning becomes a one-way decision. Over-provisioning results in resources that cannot be reclaimed. Under-provisioning means that even after increasing the size, it will take a minimum of 6 hours before further expansion is possible.
Tiered Storage: This feature maintains a low-cost tier separate from the primary tier, automatically migrating log segments that have exceeded their retention period to the low-cost tier. This functionality will be discussed in detail in Section 4.
Provisioned Storage Throughput: This feature explicitly reserves throughput for EBS volumes. It can only be enabled under specific conditions: the broker size must be
kafka.m5.4xlarge or greater, or kafka.m7g.2xlarge or greater, and the volume must be 10 GiB or larger. The default value is 250 MiB per second, and each broker size has a defined maximum throughput limit.This feature has two easily overlooked prerequisites.
First, changing a single setting is not sufficient to enable it.
You can update your Amazon MSK configuration either before or after you turn on provisioned throughput. However, you won't see the desired throughput until you perform both actions: update the num.replica.fetchers configuration parameter and turn on provisioned throughput.The default value for
num.replica.fetchers is 2. Even if provisioned throughput is enabled, this value must be increased to achieve the desired throughput. Both settings must be configured for the feature to function effectively.It's worth noting that the Developer Guide lists a table with recommended values for
num.replica.fetchers, but it only includes sizes in the kafka.m5 family. The table listing throughput limits includes sizes in the kafka.m7g family. The two tables on the same page cover different ranges of broker sizes. When using kafka.m7g instances, it's advisable to use the corresponding values for the equivalent kafka.m5 instance as a starting point.Second, it takes time for the feature to take effect.
Your updated configuration may not take effect for up to 24 hours, and may take longer when a source volume is not fully utilized. However, transitional volume performance at least equals the performance of source storage volumes during the migration period. A fully-utilized 1 TiB volume typically takes about six hours to migrate to an updated configuration.Enabling it under heavy load will not yield immediate results. While the performance during the migration process will be equivalent to or better than the original volume, there will be a delay before any improvement is observed.
Auto-scaling. You can configure policies to automatically expand volumes based on storage utilization. This feature only supports expansion, not reduction. The cooldown period also applies to auto-scaling.
Storage capacity alerts. This feature monitors remaining storage space and triggers alerts.
All of these features are a direct result of the fact that storage capacity is finite. Because storage is limited, estimations are necessary. When those estimations are inaccurate, expansion is required. And because expansion takes time, monitoring is essential.
3.3 There Are Three Bottlenecks
The reasons why standard brokers reach their throughput limits are not singular. The Developer Guide identifies three potential causes.There are multiple causes of bottlenecks in broker throughput: volume throughput, Amazon EC2 to Amazon EBS network throughput, and Amazon EC2 egress throughput. You can enable provisioned storage throughput to adjust volume throughput. However, broker throughput limitations can be caused by Amazon EC2 to Amazon EBS network throughput and Amazon EC2 egress throughput.Provisioned storage throughput adjusts only one of these three. The remaining two are set by the broker size. The number of consumer groups and the number of consumers in each group drive EC2 egress throughput.
Sizing Standard brokers therefore spans three layers of calculation. Which one gives out first as readers are added depends on which of the three reaches its ceiling first.
With Express brokers, this three-layer calculation disappears. Because storage is separated out, the ceiling for a broker size is given directly as a throughput figure. Section 5 shows that shape.
3.4 What Express Brokers Hand to Amazon MSK
The Express brokers page states that Amazon MSK took all five of these over at once.No storage management: Express brokers eliminate the need to provision or manage any storage resources. You get elastic, virtually unlimited, pay-as-you-go, and fully managed storage. For high throughput use cases, you do not need to reason about the interactions between compute instances and storage volumes, and the associated throughput bottlenecks.A similar note appears in the Storage Management section.
With Express brokers, you don't need to provision or manage any storage resoures used for your data. This simplifies cluster management and eliminates one of the common causes of operational issues with Apache Kafka clusters.Amazon MSK took over all five operations. Specifying a volume size, configuring tiering, reserving throughput, setting an auto-scaling policy, and alerting on remaining capacity are all absent from Express brokers.
Consequently, there is only one decision to be made regarding storage: the retention period for each topic. Once you set the retention period, the service matches the capacity behind it. You decide the size and the number of brokers on Express brokers as well. This is a key difference from MSK Serverless.
3.5 What the Handover Takes Away
A handover is the disappearance of an operation. When five operations disappear, the practices that depended on them disappear with them.| Practice That Worked on Standard | How Express Handles It |
|---|---|
| Shortening retention on the primary tier while extending the low-cost tier | The adjustment itself does not exist, because there is no tier. |
| Provisioning EBS throughput to clear a write bottleneck | The operation does not exist, because the bottleneck sits elsewhere. |
| Using a storage utilization alarm as the starting point for capacity planning | Utilization disappears as a concept. Throughput becomes the starting point for monitoring. |
| Taking a generous volume now to cover future growth | There is no up-front allocation. You pay for what you use. |
Creating a small validation cluster using kafka.t3.small | The T3 family is not supported. Express only supports M7g instances. |
The last row is easily overlooked. Express brokers only support M7g instances. A common practice of creating validation environments using small, burstable instances is not possible with Express.
3.6 What Does Not Change When the Broker Type Changes
Having set out the differences, it is worth fixing what does not change. The wider the range that does not change, the narrower the material for the decision.| Item | Relationship between Standard and Express |
|---|---|
| Apache Kafka APIs and Protocols | Identical. No changes are required for client applications. |
| Authentication and Authorization Methods | The same. IAM, SASL/SCRAM, mTLS, plaintext, and Kafka's access control lists. |
| Encryption | The same. For both data at rest and in transit. |
| Connection Paths | The same. Both private and public access. |
| Monitoring | The same. CloudWatch and Open Monitoring. |
| Scaling Direction | The same. Both vertical and horizontal scaling. |
| Maximum Number of IAM Authenticated Connections per Broker | The same. 3000. |
| Maximum Number of Brokers per Cluster | The same. 30 for ZooKeeper-based clusters, and 60 for KRaft-based clusters. |
There is a difference in connection rates. With IAM authentication, Express brokers can handle 100 connections per second. Standard brokers also achieve 100 connections per second on the M5 and M7g instance families, but only 4 on the T3 family. Only the T3 family exhibits this significantly lower rate. This difference is due to the instance family, not the broker type itself. However, Express does not offer the T3 family, so this limitation does not exist for Express brokers.
Regarding monitoring, an additional point of consideration is necessary. Both the Standard and Express options in the comparison table list CloudWatch and Open Monitoring. The methods are the same. However, the Amazon MSK Developer Guide publishes separate lists of CloudWatch metrics, one for Standard brokers and one for Express brokers. Despite this, the monitoring levels –
DEFAULT, PER_BROKER, PER_TOPIC_PER_BROKER, and PER_TOPIC_PER_PARTITION – are consistent across both.Even if the methods are the same, the list of metrics produced may not always be identical. Storage utilization is a prime example. In Standard brokers, disk usage is often a central focus of monitoring. However, with Express brokers, this consideration disappears entirely since users do not manage their own storage. If you plan to reuse dashboards and alerts across different broker types, it's necessary to compare the two lists of metrics to ensure compatibility.
4. Tiered Storage Is Not the Built-in Storage of Express Brokers
This section is the core of this article.4.1 Tiered Storage Is a Feature of Standard Brokers
The title of the page in the Amazon MSK Developer Guide that describes tiered storage is as follows:Tiered storage for Standard brokersThe title says Standard brokers. In the comparison table from Section 3 as well, tiered storage sits on the Standard side of Storage Management. The Express side says only Fully MSK managed.
What tiered storage does is explained at the beginning of the same page:
Amazon MSK stores streaming data in a performance-optimized primary storage tier until it reaches the Apache Kafka topic retention limits. Then, Amazon MSK automatically moves data into the new low-cost storage tier.This feature corresponds to a proposal on the Apache Kafka side.
This feature is compatible with the APIs introduced in KIP-405: Kafka Tiered Storage.4.2 What Tiered Storage Tiers
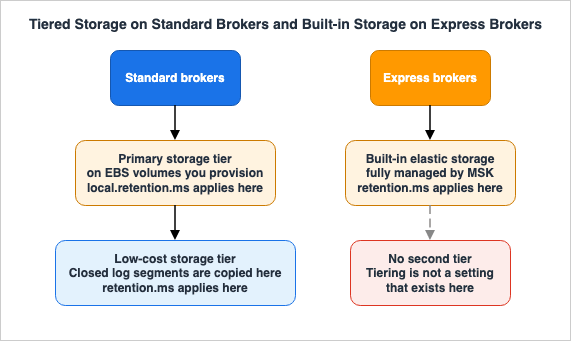
Tiered storage tiers log segments. It does not tier topics or partitions.Apache Kafka writes messages to files called log segments. When a segment is closed, tiered storage replicates that segment to a low-cost tier. Once the segment meets the local retention criteria, it is removed from the primary tier.
Therefore, the configuration for tiered storage consists of two retention periods.
| Setting | Meaning |
|---|---|
retention.ms and retention.bytes | Overall retention, including the low-cost tier. |
local.retention.ms and local.retention.bytes | Retention on the primary tier. |
There is a constraint between these two settings.
local.retention cannot equal or exceed retention. The default value for local.retention is -2, which means it uses the value of retention. If left at the default, data exists in both the primary and low-cost tiers, and both expire simultaneously. In other words, if left at the default, the low-cost tier simply becomes a duplicate. This does not provide any cost savings. To achieve cost savings, you must explicitly shorten the local.retention period.The minimum retention period for the low-cost tier is 3 days. There is no minimum retention period for the primary tier.
Log segments also have a minimum size. For topics with tiered storage enabled, the minimum size of a log segment is 48 MiB, or the minimum roll time is 10 minutes. These correspond to the
segment.bytes and segment.ms settings. A topic that runs with small segments cannot be tiered as it stands.Read behavior also changes.
When your application starts reading data from the tiered storage, you can expect an increase in read latency for the first few bytes. As you start reading the remaining data sequentially from the low-cost tier, you can expect latencies that are similar to the primary storage tier.There is a slight delay for the first few bytes. After that, read performance is comparable to the primary tier. This is designed with use cases involving re-processing historical data in mind.
4.3 Activation Takes Two Steps, Cluster and Topic
Enabling tiered storage is not a single action. There is one action on the cluster side and another on the topic side. The same confusion happens here.On the cluster side, the action is setting the storage mode to
TIERED.aws kafka update-storage --current-version Current-Cluster-Version --cluster-arn Cluster-arn --storage-mode TIEREDThis action has a prerequisite.
You can enable tiered storage only if your cluster's log.cleanup.policy is set to delete, as compacted topics are not supported on tiered storage. Later, you can configure an individual topic's log.cleanup.policy to compact if tiered storage is not enabled on that particular topic.If the cluster's cleanup policy is not
delete, the cluster-side activation itself cannot be performed. On top of that, a topic that does not have tiered storage enabled can still use the compact policy.On the topic side, the action involves setting
remote.storage.enable to true. This is also the time when retention periods are configured.bin/kafka-configs.sh --bootstrap-server $bsrv --alter --entity-type topics --entity-name msk-ts-topic --add-config 'remote.storage.enable=true, local.retention.ms=604800000, retention.ms=15550000000'Enabling tiered storage on the cluster does not tier the data of existing topics. Tiered storage has to be enabled topic by topic. Put the other way round, one cluster can hold both tiered topics and untiered ones.
These two steps explain the asymmetry in the constraints that Section 4.4 covers. Deactivation works per topic and not for the whole cluster because activation takes this shape.
4.4 Prerequisites Before Starting and Constraints After Activation
Tiered storage has both prerequisites for activation and constraints that apply after activation. These prerequisites extend to the client-side as well.You must use Apache Kafka client version 3.0.0 or higher to create a new topic with tiered storage enabled.The Amazon MSK cluster with tiered storage enabled must use version 3.6.0 or higher, or 2.8.2.tiered.In addition to the cluster-side requirements, there are also conditions that apply to the client version used to create topics. These conditions only apply when creating new topics. The Developer Guide states the following regarding migrating existing topics to tiered storage:
When you enable tiered storage on an already existing topic, you aren't restricted to a certain Apache Kafka client version.Each constraint that applies after activation shapes how you operate.
| Constraint | Description |
|---|---|
| Region | Not available in AWS GovCloud (US) Regions. |
| Broker Size | Not available with t3.small brokers. |
| Cleanup Policy | Not available for compacted topics. The cleanup.policy for topics being tiered must be set to delete. |
| Policy Changes | After a topic is created in a tiered storage cluster, the log.cleanup.policy cannot be modified. |
| Log Directories | Does not support multiple log directories on the broker. |
| Version Migration | On 2.8.2.tiered, you can migrate only to another Apache Kafka version that supports tiered storage. That version has already reached end of support. |
| Isolation Level | When reading from the low-cost tier, the client must not be set to read_committed, unless actually using transactional features. |
| Capacity Visibility | The kafka-log-dirs tool will not report the size of data in the low-cost tier; it only returns the size of log segments in the primary tier. |
The final point directly impacts operational design. If your operations currently rely on using
kafka-log-dirs to monitor disk usage, after enabling tiered storage, you will only see the size of the primary tier. You will need to provide an alternative method for determining the total capacity.4.5 The Built-in Storage of Express Brokers Is Not a Tier
The storage in Express brokers is a single elastic store with virtually no upper limit. There is no tier.Therefore, the following do not exist within Express brokers:
- Any operation to enable tiering.
- The settings
local.retention.msandlocal.retention.bytes. - Combinations of retention periods for primary and low-cost tiers.
- The behavior of increased latency for the first few bytes read from the low-cost tier.
- The limitation of a minimum 3-day retention period for the low-cost tier.
What is absent is the concept itself. It is not that a setting sits at a default value. There is no such thing as an Express cluster with tiered storage turned off. An Express cluster has no tier to begin with.
4.6 Why the Two Are Confused
The two features make the same promise to the reader: storage with virtually no upper limit. Because the promise is the same, they read as two names for one feature.Furthermore, the limitations described in the Developer Guide contribute to this confusion. The list of limitations for tiered storage includes the following sentence:
Tiered storage applies only to provisioned mode clusters.The only thing this sentence excludes is MSK Serverless. Express brokers are provisioned mode clusters too, so this sentence on its own reads as though Express can use it. The page title and the comparison table say it is a Standard-side feature, which leaves two statements of different strength standing side by side in the same document. Section 11 covers this point.
4.7 Where a Design Built on the Confusion Gets Stuck
The confusion does not surface while the design is being written. It surfaces in three places.The first is the review of a retention design. Say the design calls for 4 hours on the primary tier and 30 days overall. If Express is the choice, no setting exists to express that design. The only value you can write is the overall retention period. It gets stuck in the form of a design that is too fine-grained. It is not that the design itself fails.
The second is explaining the cost structure. Tiered storage bills on the amount stored and the amount retrieved. The built-in storage of Express bills on the amount stored and the amount ingested. The axes differ, so an estimate built for one does not transfer to the other.
The third is moving off an existing cluster. When a Standard cluster that uses tiered storage moves to Express, the tiered storage settings do not come across. More precisely, there is nowhere for them to land. In the work of copying topic settings, these two settings are the ones that lose their destination.
4.8 How to Tell Whether Your Configuration Has Tiered Storage
You can determine whether your configuration includes tiered storage by following these steps:- If your cluster type is MSK Serverless, tiered storage is not present.
- If your cluster type is MSK Provisioned and the broker instance type begins with
express., tiered storage is not present. - If your cluster type is MSK Provisioned and the broker instance type begins with
kafka., you can use tiered storage. However,kafka.t3.smallis not supported. - Tiered storage is not available in AWS GovCloud (US) Regions.
- The cluster's Apache Kafka version must be 3.6.0 or higher, or
2.8.2.tiered.
The same entry point shows up in the API's
StorageMode. The StorageMode in UpdateStorage accepts exactly two values, LOCAL and TIERED. Those two values live inside the world of Standard brokers. They are not two of three values that would include Express.5. What Choosing Express Brokers Takes Away
This section lists what becomes unavailable the moment you choose Express brokers, and only what a primary source confirms. The starting point is the additional information enumerated on the Amazon MSK Express brokers page.* Express brokers work with Apache Kafka APIs, but don't yet fully support KStreams API.
* Express brokers are only available in a 3AZs configuration.
* Express brokers are only available on select instance sizes. See Amazon MSK pricing for the updated list.
* Express brokers are supported on the following Apache Kafka versions: 3.6, 3.8, 3.9, and 4.2.
* Express brokers can be created with KRaft mode from Apache Kafka version 3.9 onwards.
* KIP-932: Queues for Kafka is not yet supported on Express brokers.5.1 A Configuration on Two Availability Zones
Express brokers can only be created across three Availability Zones. The page that states the prerequisites for cluster creation spells the condition out in more detail.For Standard brokers in the US West (N. California) Region, you need two subnets in two different Availability Zones. In all other Regions where Amazon MSK is available, you can specify either two or three subnets. Your subnets must all be in different Availability Zones. For Express brokers, you need three subnets in three different Availability Zones.This one sentence branches three ways. Standard brokers can generally choose two or three subnets. The US West (N. California) Region alone is limited to two. Express brokers need three. In every case the subnets sit in separate Availability Zones.
Being fixed at three zones is an advantage from an availability point of view. It is also a constraint. If your situation requires using only two zones, you cannot choose Express brokers. This might be the case if your subnet design is already constrained to two zones, or if there are no available IP addresses in the third zone.
Amazon MSK does not let you create a cluster in a single Availability Zone with either broker type.
5.2 Kafka Settings Fixed as Read-Only
Apache Kafka has hundreds of broker settings. The Amazon MSK Developer Guide states that Express brokers protect the critical ones among them.Express brokers improve the availability and durability of your MSK Provisioned clusters by setting optimal values for critical configurations and protecting them from common misconfiguration. There are three categories of configurations based on read and write access: read/write (editable), read only, and non-read/write configurations.These settings are categorized into three groups: those that can be both read and written, those that are read-only, and those that are neither. The third category refers to settings that cannot be read or written.
Settings that can be both read and written are further divided into static and dynamic settings. Static settings require a broker restart to take effect, while dynamic settings do not. Settings such as
auto.create.topics.enable, log.retention.ms, compression.type, and replica.selector.class fall into this category. The custom.advertised.listeners setting, used to configure custom domain names, is also a setting that can be both read and written.There are 17 settings that are fixed as read-only. However, the actual values are version-dependent. The Developer Guide includes this disclaimer at the beginning of the list.
These values may change depending on the Apache Kafka version running on the cluster, so remember to check the values from your specific cluster.Of these 17, the following 4 settings are the ones that influence design decisions:
| Property | Value in Express |
|---|---|
default.replication.factor | 3 |
min.insync.replicas | 2 |
unclean.leader.election.enable | FALSE |
transaction.state.log.min.isr | 2 |
These 4 settings are core configurations that determine the trade-offs between Kafka's durability and availability. They cannot be modified in Express.
There are limited scenarios where this restriction poses a problem. For example, a design that reduces costs by lowering the replication factor to 2, a design that prioritizes write availability by setting
min.insync.replicas to 1, or a design that enables unclean.leader.election and accepts some data loss in exchange for increased availability. These configurations can only be expressed in Standard.The
listeners setting is also read-only. However, the advertised.listeners setting can be configured. Configurations that use custom domain names can still be implemented in Express using the custom.advertised.listeners setting.num.io.threads and num.network.threads are automatically determined based on the instance size. On Standard brokers there is a practice of tuning these two by hand, and the procedure is documented officially. On Express the tuning work disappears along with the setting.5.3 Some of the Kafka Versions
The supported versions for Express brokers are 3.6, 3.8, 3.9, and 4.2.This list is not continuous. 3.7 is missing. 4.0 and 4.1 are not on it either. Yet the Kafka versions row of the comparison table from Section 3 says this about Express.
Starts at version 3.6Read that as 3.6 and later and it takes in 3.7, 4.0, and 4.1 as well. The actual list is not continuous. The wording of the comparison table and the list on the feature page describe ranges of different shapes. Section 11 covers this point.
Furthermore, being on the list and being worth choosing today are two different things. The end of support for Apache Kafka 3.6.0 on Amazon MSK is June 1, 2026, which has already passed as of August 22, 2026, the date this article was checked. Amazon MSK's version support policy states the following regarding clusters that have passed their support end date:
A cluster using a Kafka version after its end of support date is auto-upgraded to the recommended Kafka version. Automatic upgrades can happen at any time after the end of support date. You will not receive any notification before the upgrade.They may be automatically upgraded at any time, without prior notice. There is no reason to choose this version for newly created clusters. The dates themselves live in the AWS End-of-Support and EOL Reference, so confirm them there.
5.4 Share Groups Introduced by KIP-932
KIP-932 in Apache Kafka is the proposal that introduces share groups under the titleQueues for Kafka. Its current state on the Apache Wiki is Accepted. It lets several consumers read the partitions of one topic without exclusive assignment, which brings the usage closer to a traditional message queue.The Apache Kafka 4.0 release announcement offers this feature as early access. The Amazon MSK description of 4.1.x uses the word preview. Either way, it is not generally available.
Furthermore, there is explicit mention of Express brokers.
KIP-932: Queues for Kafka is not yet supported on Express brokers.If queue semantics are in the requirements, Express is not available for it today.
5.5 The Caveat About Kafka Streams
The Express brokers page contains the following sentence:Express brokers work with Apache Kafka APIs, but don't yet fully support KStreams API.This sentence is a statement of degree. It says support is not yet full. It does not say the API is unusable. This article will also avoid making stronger claims than those found in the original source.
At the same time, the What's New post dated June 8, 2026, announces a step forward for Kafka Streams on Express brokers.
Effective today, Amazon MSK Express Brokers support automatic topic creation with Kafka Streams.Kafka Streams uses internal topics to hold state and to repartition data. Until then those topics had to be created by hand on Express. That requirement is gone.
Both the comprehensive disclaimer in the Developer Guide and this specific advancement coexist. If you are planning to deploy Kafka Streams applications on Express, you should read both documents and verify the functionality relevant to your use case.
The name used by Apache Kafka itself is Kafka Streams. The spelling
KStreams does not appear on the Apache side.5.6 Manual Partition Reassignment
On an Express brokers cluster, Intelligent Rebalancing is on by default. The service continuously monitors partition placement and automatically rebalances them when imbalances are detected.What is enabled by default is a newly created cluster. The Developer Guide states that on Express clusters created before November 20, 2025, the feature is offered with Rebalancing Status set to Paused. You switch it to Active from the console, the AWS CLI, or an SDK. If you already run such a cluster, check first whether the feature is on.
This feature is exclusive with other means.
If intelligent rebalancing is turned on, you won't be able to use third-party tools, such as Cruise Control, for partition rebalancing. You must first pause intelligent rebalancing to use the partition reassignment API provided by these third-party tools.Bringing in an operation that uses Cruise Control means pausing Intelligent Rebalancing first.
The treatment of
kafka-reassign-partitions.sh, which ships with Apache Kafka, differs in strength between sources. Section 11 covers this point.5.7 Running Above the Ceiling
Express brokers impose explicit quotas on client throughput.Express brokers come pre-configured with Amazon MSK's best practice defaults and enforce client throughput quotas to minimize resource contention between clients and Kafka's background operations.These quotas have two tiers: sustained performance and maximum quota.
| Tier | Meaning |
|---|---|
| Sustained performance | The threshold up to which performance will not degrade. |
| Maximum quota | The threshold at which the cluster begins to throttle read and write traffic. |
While exceeding the sustained performance level may sometimes result in higher throughput, it can also lead to performance degradation. When the maximum quota is reached, throttling is applied. Applications cannot operate above this threshold.
The values are set per instance size. On the largest size,
express.m7g.16xlarge, sustained performance is 500 MBps of ingress and 1000 MBps of egress. The Express brokers page also displays these figures, comparing them to those for Standard brokers.Higher throughput: Express brokers offer up to 3x more throughput per broker than Standard brokers. For example, you can safely write data at up to 500 MBps with each m7g.16xlarge sized Express broker compared to 153.8 MBps on the equivalent Standard broker (both numbers assume sufficient bandwidth allocation towards background operations, such as replication and rebalancing).The 500 MBps and 153.8 MBps figures are values published by AWS. This article has not measured them. The parenthetical notes are also taken from the original source and represent values based on the assumption that sufficient bandwidth is allocated to background processes such as replication and rebalancing.
There are also two tiers for the maximum number of partitions. For each broker size, two values are defined: a recommended number and a maximum limit that should not be exceeded. While the recommended value is a guideline, the maximum value cannot be surpassed.
This structure is what separates Express brokers from Standard brokers. On Standard brokers the ceiling is not implemented as a throttle, so going past it shows up as degraded performance. On Express brokers the range that degrades and the range that gets throttled are separated from the start. You gain predictability, and you lose the option of running above the ceiling anyway.
Confirm the specific values on the quotas page. The reason this article carries no list is that the values move. The partition limit for Express brokers was raised by up to five times in July 2025, and the number of supported instance sizes has also increased from three to seven since the initial general availability.
5.8 What Express Brokers Take Away, Collected
This table lists items that become unavailable when selecting Express brokers.| What Becomes Unavailable | On What Grounds |
|---|---|
| A two-zone configuration | Express brokers need three subnets. |
| The T3 and M5 instance families | Only M7g is supported. |
| Changing the replication factor, minISR, or unclean leader election | Included in the read-only configurations. |
| Adjusting the I/O thread count and the network thread count | Determined automatically from the instance size. |
| Specifying and growing an EBS volume size | Amazon MSK manages the storage. |
| Tiered storage tier settings | A feature of Standard brokers. |
| Provisioned storage throughput | A feature of Standard brokers. |
| A storage auto-scaling policy | A feature of Standard brokers. |
| A storage capacity alert | Amazon MSK manages the storage, so utilization is not a concept. |
| Kafka versions 3.7, 4.0, and 4.1 | Not on the list of supported versions for Express. |
| KIP-932 share groups | Stated as not yet supported. |
| Rebalancing with Cruise Control | Intelligent Rebalancing has to be paused first. |
6. What Choosing Standard Brokers Takes Away
The subject of what a choice takes away holds in the other direction as well. Choosing Standard brokers also makes some features unavailable. What is more, that set has grown over the past year.6.1 Delivering to S3 Tables and Directly to S3 Buckets
Amazon MSK offers the ability to deliver topic content externally without requiring additional infrastructure. This includes delivering to Amazon S3 Tables as Apache Iceberg tables, and delivering as objects directly to generic Amazon S3 buckets.These two options are exclusively for Express brokers.
An Amazon MSK Provisioned cluster with Express brokers. Standard brokers and Amazon MSK Serverless are not supported.Standard brokers and MSK Serverless do not support this delivery method. To achieve similar functionality, you will need to utilize either Amazon Data Firehose, Managed Service for Apache Flink, or Kafka Connect.
Of everything this article covers, this is the newest removal and the easiest one to miss. Standard brokers are often chosen for their wider configuration freedom. That freedom is traded against this delivery path.
6.2 Intelligent Rebalancing
Intelligent Rebalancing is a feature of Express brokers. It is unavailable on Standard brokers even though those are MSK Provisioned clusters too.To correct partition skew on Standard brokers, you run the partition reassignment tool yourself or bring in an external tool such as Cruise Control. The exclusivity mentioned earlier as a limitation of Express brokers also means that Standard brokers lack that level of automation.
6.3 Operating Without a Maintenance Window
Express brokers do not have maintenance windows.There are no maintenance windows for Express brokers. Amazon MSK automatically updates your cluster on an ongoing basis in a time distributed manner, meaning you can expect occasional and singular broker reboots across the month.The distributed broker restarts are visible as a
BROKER_UPDATE operation type in the console and through the DescribeClusterOperation and ListClusterOperations commands.Standard brokers require a planned maintenance window. This adds one more task to the operations team's calendar.
6.4 Apache Kafka 4.2.x
The documentation for Amazon MSK's 4.2.x versions includes a specific note.Apache Kafka version 4.2 is currently available on MSK Express brokers only.As of the date this article was checked, 4.2.x cannot be chosen on Standard brokers. In the other direction, as Section 5 showed, the list of supported versions for Express brokers does not carry 3.7, 4.0, or 4.1. Neither broker type holds every version that Amazon MSK offers.
7. KRaft Is Decided When the Cluster Is Created
7.1 The KRaft Metadata Management Approach
Apache Kafka has historically used Apache ZooKeeper for managing cluster metadata. KRaft is the consensus protocol that moves that role onto a group of controllers inside Kafka itself. The proposal is KIP-500.Amazon MSK includes the KRaft controllers at no additional cost, and they need no setup or management from you. ZooKeeper nodes get the same treatment.
7.2 The Branch on the Amazon MSK Side
Amazon MSK began supporting KRaft with Apache Kafka 3.7.x.Express brokers have a different starting point for this support.
Express brokers can be created with KRaft mode from Apache Kafka version 3.9 onwards.Both the word onwards and the words created with are doing work here. The two conditions are that the version is 3.9 or later, and that the mode is decided at creation time.
Combining these two factors, the version selection for Express brokers is as follows:
| Version Available on Express | Metadata Management |
|---|---|
| 3.6 | ZooKeeper mode only. However, it is past its end of support. |
| 3.8 | ZooKeeper mode only. |
| 3.9 | Both ZooKeeper mode and KRaft mode. |
| 4.2 | KRaft mode. This is a consequence of Apache Kafka 4.x not having a ZooKeeper mode. See Section 7.3. |
Therefore, if you want to use KRaft with Express brokers, your practical options are 3.9 and 4.2.
7.3 The Branch on the Apache Kafka Side
Read only the Amazon MSK side and KRaft looks like one of two available modes. However, when looking at the Apache Kafka side, the situation is different.The release announcement for Apache Kafka 4.0.0 states:
Apache Kafka 4.0 is a significant milestone, marking the first major release to operate entirely without Apache ZooKeeper®. By running in KRaft mode by default, Kafka simplifies deployment and management, eliminating the complexity of maintaining a separate ZooKeeper ensemble.In Apache Kafka 4.0, ZooKeeper is no longer used. Version 4.0 cannot operate in ZooKeeper mode, and migration from ZooKeeper mode is not possible. Upstream, version 3.9 is positioned as a bridging release.
The description for Amazon MSK's 3.9.x also points to the same position.
Version 3.9 is the last version to support both ZooKeeper and KRaft metadata management systems.Therefore, KRaft is the destination. It is not simply one of two possible options. Clusters built in ZooKeeper mode will eventually need to migrate, or remain on that version.
The two sources differ in how strongly they put it. The Apache Kafka side writes that 4.0 is the first major release to run without ZooKeeper. The Amazon MSK description of 4.0.x writes that it deprecates metadata management through ZooKeeper. Removal and deprecation are not the same strength. This article treats the upstream wording as authoritative. The response from
get-compatible-kafka-versions shows which options a given version actually has.7.4 Changes to the Maximum Number of Brokers
The metadata management method also affects the maximum number of brokers per cluster.| Metadata Management | Maximum Number of Brokers per Cluster |
|---|---|
| ZooKeeper-based | 30 |
| KRaft-based | 60 |
This limit applies equally to Standard brokers and Express brokers. Both can apply for an increase in the quota.
The number of partitions per broker remains the same regardless of whether using KRaft or ZooKeeper. What changes is the maximum number of brokers per cluster, which ultimately increases the total number of partitions that the entire cluster can handle.
7.5 What Changes in Operations Under KRaft
The Amazon MSK Developer Guide lists important considerations for clusters running in KRaft mode. No API changes are required. However, several operational aspects will change.| Item | Handling in KRaft Mode |
|---|---|
| Client connection string | Use --bootstrap-server. Do not use --zookeeper. Apache Kafka 2.5 deprecated --zookeeper and 3.0 removed it. |
| Access control list management | Performed with --bootstrap-server. Do not use --zookeeper. |
| Tools that connect to ZooKeeper | Check that they can use the Kafka Admin API without a ZooKeeper connection. Cruise Control has a separate procedure for KRaft. |
| Accessing the Controller | Direct access is not necessary for administrative operations. If you collect metrics with Open Monitoring, you need the controller's DNS endpoint, and ListNodes returns it. |
| CloudWatch metrics | Nothing extra has to be monitored compared with ZooKeeper mode. |
| Access control for controller nodes | Kafka's own controllers hold the metadata, so there is no separate access to control as there was with ZooKeeper nodes. |
The most significant operational impact is in the third item. If you have tools that directly connect to ZooKeeper, you will need to remove that dependency before migrating. This often applies to older versions of client libraries, tools for managing Kafka, and visualization tools.
7.6 Prerequisites for Migrating from ZooKeeper to KRaft
The Amazon MSK Developer Guide provides migration procedures for existing clusters.You can migrate an existing ZooKeeper-based MSK cluster to KRaft mode using the UpdateClusterKafkaVersion API. The migration is performed in-place — your cluster remains available throughout the process and no data is moved.There are eight prerequisites. The following five involve design decisions:
| Prerequisite | Description |
|---|---|
| Version | The cluster must be running in ZooKeeper mode with version 3.9.x. If running an earlier version, upgrade to 3.9.x first. |
| ZooKeeper client access | On Standard brokers, set ZookeeperAccess.Enabled=false with the UpdateConnectivity API before starting. Express brokers do not need this step. |
| Instance type | The cluster does not use kafka.t3.small. |
| Listeners | advertised.listeners is not set dynamically. |
| Combination | Public Access and Open Monitoring are not both enabled. |
And the most important prerequisite of all is that the migration cannot be undone.
Migration cannot be reversed. Once the cluster is migrated to KRaft mode, you cannot switch it back to ZooKeeper mode.Sources disagree on whether this migration is possible at all. Section 11 covers that point.
8. The Choices You Cannot Reverse
Amazon MSK has six choices that only move in one direction. They are decisions fixed at creation that cannot be changed, paths you can move along but cannot come back from, and quantities you can raise but cannot lower. Each is written on a different page, which makes it worth checking them together.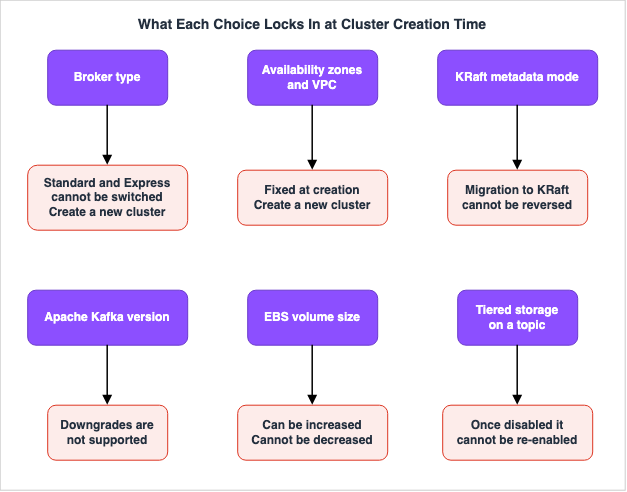
8.1 The Broker Type of the Cluster
The Amazon MSK broker types page notes:You can't change an MSK Provisioned cluster from a Standard broker type to an Express broker type by switching the broker type using the MSK API. You have to create a new cluster with the desired broker type (Standard or Express).It is not possible to change this via the API. You will need to create a new cluster with the desired broker type.
As Section 2 showed, the broker type is a series of instance types rather than a field in the API. Given this, the statement that it cannot be changed makes perfect sense.
8.2 The Move to KRaft for Metadata Management
As mentioned in Section 7, the transition to KRaft is irreversible. It is not possible to revert back to ZooKeeper mode.8.3 Tiered Storage on a Topic
The list of tiered storage limitations includes the following two points:Tiered storage can be disabled for individual topics but not for the entire cluster. Once disabled, tiered storage cannot be re-enabled for a topic.You can disable it per topic, and a topic once disabled cannot have it enabled again. Disabling it for the cluster as a whole is not possible either.
The same list also includes limitations regarding topic cleanup policies. For a topic with tiered storage enabled, the cleanup policy can only be
delete, and compacted topics cannot be used. The policy also cannot be changed after the topic is created.8.4 The Size of an EBS Volume
As Section 3 showed, an EBS volume can be increased and cannot be decreased. The cool-down period is six hours at minimum.8.5 Apache Kafka Versions
The upgrade procedure page includes two notes.Server-side upgrades don't automatically update client applications.
To maintain cluster stability, version downgrades aren't supported.A version cannot be lowered. If a compatibility problem turns up after the upgrade, it has to be dealt with on that version. And because the server side moving up does not carry the clients with it, client compatibility has to be confirmed first.
8.6 VPC and Availability Zones
The cluster creation page displays a warning at the top.You can't change the VPC for an MSK Provisioned cluster after you create the cluster.The number of Availability Zones is treated in the same way. Increasing the number of brokers involves increasing the number of brokers within each Availability Zone. It is not possible to add entirely new zones.
AWS Trusted Advisor includes a check that detects clusters with two Availability Zones, and its recommended actions clearly illustrate this behavior.
To increase availability of the cluster, you can create another cluster in a 3 AZs setup. Then migrate the existing cluster to the new cluster that you created. You can use Amazon MSK replication for this migration.To move a cluster from two Availability Zones to three, you must create a new cluster and migrate the data. This process essentially involves recreating the cluster with the desired configuration, similar to changing the broker type.
All six move in one direction only. Changing the broker type, the VPC, or the number of Availability Zones means building the cluster again. KRaft and the version can only move forward. An EBS volume and tiered storage on a topic cannot be returned to their earlier state.
8.7 What to Include in Your Broker Type Migration Plan
The inability to change the broker type dictates the structure of your migration plan. The only viable approach is to create a new cluster and migrate both data and metadata to it.The means AWS points to is MSK Replicator. It replicates topic configurations, access control lists, and consumer group offsets. However, there are several points to consider when documenting your migration plan.
| Consideration | Details |
|---|---|
| Fixed Configurations | In Express clusters, replication-factor, min.insync.replicas, and unclean.leader.election.enable are fixed to their default values. If these differ from the source cluster, they will be overwritten. |
| Read/Write Configurations | Broker-level read/write configurations should be configured separately on the target cluster as a prerequisite to the migration. |
| Access Control Lists | If you are using SASL/SCRAM or mTLS for access control instead of IAM, you will need to explicitly recreate the write access control lists. |
| Tiered Storage | As described in Section 4, tiered storage configurations cannot be migrated. |
Your migration plan should include a list of items that will not be migrated. It's best to document this list before outlining the items that will be migrated.
9. What MSK Serverless Trades
MSK Serverless does not expose the unit called a broker at all. Capacity estimation, scaling, and partition placement are all done by the service. There are things it trades away in return.9.1 The Authorization Method on MSK Serverless
MSK Serverless requires IAM access control for all clusters. Apache Kafka access control lists (ACLs) are not supported.Kafka access control lists (ACLs) cannot be used. All authorization is managed through IAM.
This consideration is important during migration. If your existing Kafka cluster uses ACLs to manage permissions, and your applications rely on those definitions, migrating to MSK Serverless will require rewriting your authorization model. With MSK Provisioned, you can use ACLs on both Standard and Express brokers.
9.2 Scope of Configuration Options with MSK Serverless
With MSK Serverless, you cannot modify broker settings. You can only change seven properties at the topic level.| Property | Default Value | Notes |
|---|---|---|
cleanup.policy | Delete | Can only be modified during topic creation. |
compression.type | Producer | |
max.message.bytes | 1048588 | Maximum value is 8388608. |
message.timestamp.difference.max.ms | long.max | |
message.timestamp.type | CreateTime | |
retention.bytes | 250 GiB | -1 indicates unlimited. |
retention.ms | 7 days | -1 indicates unlimited. |
The
segment.bytes property cannot be modified. This limitation may surface in applications using Kafka Streams. Kafka Streams may attempt to create internal topics using a segment.bytes value that MSK Serverless does not permit.9.3 MSK Serverless Quotas
MSK Serverless operates within quota limits determined on a per-cluster basis, unless otherwise stated. The following values are key considerations for design decisions:| Item | Quota |
|---|---|
| Maximum Ingestion Throughput | 200 MBps |
| Maximum Egress Throughput | 400 MBps |
| Maximum Message Size | 8 MiB |
| Maximum Number of Leader Partitions | 2400 for non-compacted topics, 120 for compacted topics |
| Maximum Number of Consumer Groups | 500 |
| Maximum Client Connections | 3000 |
| Maximum Number of Serverless Clusters per Account | 10 |
There is also a throughput ceiling per partition. Ingress is 5 MBps and egress is 10 MBps. MSK Provisioned has no such per-partition ceiling.
This difference changes the sizing procedure. On MSK Serverless you secure enough partitions at topic creation to carry the total throughput you need. For example, if you need an ingestion rate of 50 MBps, you'll need at least 10 partitions. This means increasing the number of partitions rather than increasing the number of brokers.
Amazon MSK manages partition placement. You won't need to perform any corrective actions to address imbalances. Conversely, there is no way to intentionally control partition placement.
Retention periods can be configured without limits. This does not involve estimating storage capacity. If you were to achieve the same functionality with MSK Provisioned, you would need to either provision the necessary amount of EBS volumes or enable tiered storage.
9.4 Features Available Only on Another Path
The features covered in Sections 4 and 6 are unavailable on MSK Serverless. Tiered storage is exclusively available with provisioned clusters. Only Express brokers support direct delivery to S3 Tables and delivery to general purpose S3 buckets.9.5 The Shape That Suits MSK Serverless
Having set out what MSK Serverless trades away, here is what it gets in return.- No need to estimate capacity. You don't need to determine the number or size of brokers.
- No need to manage partition placement.
- Retention periods can be unlimited.
- Pricing is based on actual throughput.
- There's no operation to specify an Apache Kafka version.
This last point is a clear distinction between MSK Serverless and MSK Provisioned. The
CreateClusterV2 structure for Serverless doesn't include a field to specify the Kafka version. With MSK Provisioned, users choose the version and manage upgrades. While you have the flexibility to decide when to upgrade, you are also responsible for making that decision. The Amazon MSK documentation overview states that serverless clusters are designed to have Amazon MSK automatically handle version upgrades.MSK Serverless therefore suits a design where demand cannot be predicted, where Kafka settings need no fine adjustment, and where authorization can be moved onto IAM. It does not suit moving an existing self-managed Kafka across with its configuration intact, because only seven settings can come with it.
10. Materializing a Topic into S3 Tables
This section stops at the wiring. The internals of the Apache Iceberg table format and the shape of the lakehouse as a whole belong to AWS Data Lakehouse Architecture Guide.10.1 What Delivery to Streaming Tables Does
Amazon MSK Express brokers can continuously materialize a Kafka topic as an Apache Iceberg table on Amazon S3 Tables. The feature was announced on July 30, 2026.The unit of delivery is a Channel. Channels are created using
CreateChannel and managed using DescribeChannel, UpdateChannel, DeleteChannel, and ListChannels. Tables are not created using CreateTable. Amazon MSK creates them during the initial delivery.10.2 Conditions for Data Delivery
| Condition | Description |
|---|---|
| Cluster | MSK Provisioned Express brokers only. Standard brokers and MSK Serverless are not supported. |
| Dead-Letter Queue | An S3 bucket is required as the destination for records that cannot be processed. |
| Schema | You need a schema registered in the AWS Glue Schema Registry. |
| Input Format | JSON or JSON_SCHEMA_GSR. |
| Region | The S3 Table bucket must be in the same AWS Region as the Amazon MSK cluster. |
| Data Freshness | Between 5 and 15 minutes. The default is 10 minutes. |
| Throughput Minimum | AWS states that for a minimum data freshness of 5 minutes, the topic should produce at least 2.4 MB per second of uncompressed data. For topics below that, raise the freshness value. |
A common oversight is the requirement for a schema registry. Even if the topic records are raw JSON, you must specify the schema ARN.
10.3 What to Understand Before Wiring It Up
Before setting up the data pipeline, you need to incorporate the following two points into the design:A Channel does not backfill previously produced data — only data produced after enablement is delivered. For streaming tables for Apache Iceberg, a Channel creates a new Iceberg table for each configuration; delivery to existing Iceberg tables is not supported.Historical data will not be delivered. Only data generated after activation will be included. If you need to incorporate existing data already accumulated in topics into a table, you will need to use a different method.
Data cannot be delivered to existing Iceberg tables. Each channel will create a new table based on its configuration. A design that appends data to existing tables is not feasible.
Furthermore, schema evolution is not supported. Partitioning is time-based. Amazon MSK writes the table, so the table is read-only. S3 Tables handles table maintenance.
10.4 The Quotas That Bear on the Delivery Design
Channels carry quotas. This table lists only the values that would send you back to redesign.| Item | Quota | Adjustable? |
|---|---|---|
| Number of Channels per Amazon MSK Cluster | 50 | Yes |
| Number of Channels per Kafka Topic | 10 | Yes |
| Data Freshness Lower and Upper Limits | 5 to 15 minutes | No |
| Maximum Throughput per Channel | 10 GB per second | No |
| Maximum Number of Partitions per S3 Table | 100 | No |
| Schema Evolution | Not Supported | No |
The ability to create up to 10 Channels per topic provides flexibility in the design. A single topic can be branched to multiple destinations. Furthermore, delivery does not consume broker throughput.
No broker impact — A channel reads from the topic without consuming broker throughput or affecting producer and consumer workloads.This property is the single biggest difference from a configuration that stands up a connector separately. A connector is a consumer, so it uses egress throughput in proportion to what it reads from the broker. A Channel does not.
However, the lack of support for schema evolution significantly influences design decisions. This delivery path cannot accommodate designs that rely on topic schema changes.
10.5 The Line Against the Article That Covers the Consumer Side
This feature is one of the paths that consume Kafka, but what this article covers stops at the conditions on the cluster side. EventBridge Pipes Event-Driven Architecture Implementation Patterns covers the wiring that passes events from Amazon MSK to Lambda or Step Functions. AWS Real-Time Streaming Data Pipeline Architecture Guide covers the design for stream processing with Flink.11. Where the Primary Sources Disagree
Cross-check the primary sources across three lines and disagreements appear. The disagreement itself is information for the reader. Where it is not possible to decide which side is right, this article states both and decides neither.11.1 The Positioning of Express Brokers Is Written Two Opposite Ways
This discrepancy is the most significant issue within this section.The
BrokerType enumeration within the AWS CDK module for Amazon MSK describes STANDARD and EXPRESS as follows:Standard brokers provide high-availability guarantees.Express brokers are a low-cost option for development, testing, and workloads that don't require the high availability guarantees of standard MSK cluster.It states that Standard offers high availability guarantees, while Express is intended for development and testing workloads that do not require high availability.
The Amazon MSK Developer Guide says the opposite. As quoted in Section 2, it holds that Express brokers offer more resilience. The Express brokers page carries an item headed
Configured for high resilience, and the replication factor is fixed at 3, min.insync.replicas at 2, and unclean.leader.election.enable at FALSE. Data is always replicated across three Availability Zones.The AWS official blog goes further.
With this in mind, we recommend MSK Express brokers for almost all MSK workloads.Carry this disagreement into a design and you place production on Standard brokers and development on Express brokers. The Developer Guide and the AWS official blog point the other way.
Note that the CDK module in question is alpha and is explicitly marked experimental. The CDK is official AWS documentation, but it is not the primary source for the Amazon MSK specification. This article treats the Amazon MSK Developer Guide as authoritative for every statement about the specification.
11.2 The Concept of Broker Type
As Section 2 showed, the Amazon MSK API has no field for specifying a broker type. The broker type is expressed by the prefix of the instance type.In contrast, CDK has an enumeration called
BrokerType, which defines the values STANDARD and EXPRESS.The wrapper is adding an abstraction that is not present in the service's API. This structure is prone to creating discrepancies, as described in Section 11.1. Because the CDK side writes the text of the enumeration, it moves on a schedule of its own rather than with the documentation on the service side.
11.3 How the Supported Version Range for Express Is Written
The comparison table lists the Express Kafka versions asStarts at version 3.6, indicating a continuous range.The list on the feature page reads 3.6, 3.8, 3.9, and 4.2. It is not continuous.
Furthermore, the description for version 4.2.x includes the note
Apache Kafka version 4.2 is currently available on MSK Express brokers only. A version that exists only on Express and a version that exists only on Standard are in force at the same time.11.4 The CDK Constraint List Has Not Kept Up With the Service
The Amazon MSK module in the CDK enumerates the constraints that apply when using Express brokers. Held against what the service says as of the date this article was checked, three of them disagree.| CDK Description | Service Documentation |
|---|---|
| Supported Apache Kafka versions: 3.6.x, 3.8.x, 3.9.x | The Developer Guide lists versions 3.6, 3.8, 3.9, and 4.2. |
logging is not supported | A What's New post dated February 11, 2026, announced broker logs for Express brokers. |
| Lists 6 broker sizes | The quotas page lists 7, from express.m7g.large to express.m7g.16xlarge. |
Constraints picked up from the CDK text are not carried into this article. This article took every one of them again from the Amazon MSK Developer Guide and the quotas page.
11.5 Whether the ZooKeeper to KRaft Migration Is Possible at All
The Amazon MSK Developer Guide includes a dedicated migration page. As quoted in Section 7, it states that an in-place migration is possible usingUpdateClusterKafkaVersion, and that the cluster remains accessible during the migration process, with no data movement.The operations skill that AWS publishes for Amazon MSK answers the same question differently.
direct upgrades not supported today, migrate with MSK Replicator, in-place upgrade support for ZooKeeper to KRaft is planned for the future in MSKIt says that a direct upgrade is not supported today, that MSK Replicator performs the migration, and that in-place support is coming in the future. That sits head-on against the Developer Guide.
When a migration is on the table, check both the migration page in the Developer Guide and the output of
get-compatible-kafka-versions immediately before you run it. The second one returns the KRaft target versions that the cluster in question can actually migrate to. That is an answer about your cluster rather than a general statement in a document.11.6 The Regions Where Tiered Storage Is Available
The Amazon MSK feature page states the following.The feature is supported in all AWS Regions where Amazon MSK is available.The Developer Guide list of limitations states the following:
Tiered storage isn't available in AWS GovCloud (US) regions.Amazon MSK is available in both AWS GovCloud (US) Regions, and Express brokers reached them in September 2025. This disagreement therefore reaches a real decision for anyone running Amazon MSK in GovCloud.
11.7 How the Scope of Tiered Storage Is Worded
As mentioned in Section 4, the constraint list states thatTiered storage applies only to provisioned mode clusters. This excludes MSK Serverless. The page title, Tiered storage for Standard brokers, and the comparison table indicate that this feature applies to Standard brokers.Within the same documentation set, the scope of applicability is described in two different ways. This article treats the page title and comparison table as the correct information. The statement in the constraint list appears to be a remnant from a time before Express brokers were introduced.
11.8 Kafka Streams Terminology
The Amazon MSK Developer Guide section on Express brokers refers to theKStreams API.The name used in the official Apache Kafka documentation is Kafka Streams. The spelling
KStreams is not used there. KStream is the name of a type within the Kafka Streams DSL, and is not a component name.The AWS What's New post dated June 8, 2026, writes Kafka Streams correctly. Even inside the AWS documentation the spelling is not consistent.
11.9 How the Partition Reassignment Tool Is Treated
The Intelligent Rebalancing page puts it two ways. The note attached to the feature description names third-party tools as the thing it is exclusive with, and gives Cruise Control as the example. The Considerations section on the same page also takes in the partition reassignment API.You can't use partition reassignment APIs or third-party rebalancing tools when intelligent
rebalancing is enabled. To use such APIs or third-party tools, you must first pause
intelligent rebalancing for your MSK Express-based cluster.The page detailing best practices for Express brokers states the following regarding partition movement:
To move partitions to different brokers on the same MSK Provisioned cluster, you can use the partition reassignment tool named kafka-reassign-partitions.sh. We recommend that you don't reassign more than 20 partitions in a single kafka-reassign-partitions call for safe operations.kafka-reassign-partitions.sh is a tool included with Apache Kafka and is not a third-party tool. The best practices page does not mention its relationship with Intelligent Rebalancing.The operations skill that AWS publishes for Amazon MSK stands on the same side as the Considerations section.
When Intelligent Rebalancing is enabled, you cannot manually reassign partitions using `kafka-reassign-partitions.sh`. Manual partition reassignment is only available if Intelligent Rebalancing is disabled.The split is not only between documents. The Intelligent Rebalancing page is split within itself. The best practices page recommends the tool without touching the restriction, the note on the Intelligent Rebalancing page names only third-party tools, and the Considerations section and the skill both take in the API that the tool shipped with Apache Kafka uses.
If manual reassignment is going into your operational procedure, try it on the cluster in question and confirm the behavior first.
11.10 The Regions Where MSK Serverless Is Available
The opening of the MSK Serverless documentation page carries a note on available Regions, and it enumerates 14.The April 2026 edition of AWS What's New announced the addition of MSK Serverless to 13 more Regions. A previous announcement in March 2026 also listed a greater number of Regions than those included in the Developer Guide.
The list of Regions in the Developer Guide has not kept up with the announcements. That is why this article builds no list of Regions. Confirm availability in the Region table for AWS services rather than in an article.
11.11 Prioritizing When Discrepancies Arise
When discrepancies occur, there are patterns to how they manifest. Understanding these patterns can eliminate the need to re-evaluate your choices each time.| Pattern | Example | Which to Take |
|---|---|---|
| Overview Page vs. Feature-Specific Page | The Starts at version 3.6 entry in a comparison table, versus the version list on an Express page. | Feature-Specific Page. Overviews are often simplified. |
| Feature Introduction Page vs. Developer Guide | The Regions where tiered storage is offered. | Developer Guide. Text describing limitations is generally more accurate. |
| Wrapper vs. Core Service | CDK documentation versus the Amazon MSK Developer Guide. | Core Service. Wrappers are often updated on a different release cycle. |
| Outdated Information Remains | Tiered storage applies only to provisioned mode clusters. | The page describing the new feature. Descriptions written before the introduction of Express may have broader applicability. |
| Two Wordings on One Page | What Intelligent Rebalancing is exclusive with. | The wider of the two. A note beside a feature description can name only the common case. |
| Documentation vs. Actual Response | Whether a cluster can be migrated to KRaft. | The API response. Some APIs, such as get-compatible-kafka-versions, return answers specific to a given cluster. |
The last row is the strongest. When the thing being decided is your own cluster, asking the cluster is often faster than reading two documents against each other.
12. A Checklist Before You Create the Cluster
Work through the following in order before creating the cluster. The order matters. The first four can only be decided before the cluster exists.- How many Availability Zones can you use? If only two are available, Express brokers cannot be selected.
- Which broker type will you use? It cannot be switched later via the API. If you need to switch, you will need to recreate the cluster.
- Will metadata management use KRaft? This is determined at creation time. With Express brokers, it can only be selected if created on version 3.9 or later. Switching from ZooKeeper mode is irreversible.
- Which VPC will it sit in? It cannot be changed after creation.
- Which Kafka version will you choose? The available options depend on the chosen broker type. Avoid selecting versions that have reached their end of support.
- Is there a Kafka setting you need to change? If you want to change the replication factor,
min.insync.replicas, orunclean.leader.election.enablefrom their default values, you must use Standard brokers. - Is storage tiering in the requirements? If the primary tier and the overall retention need separate periods, that means Standard brokers. Otherwise, Express brokers will manage the storage.
- Will you use delivery to S3 Tables or to an S3 bucket? If so, you must use Express brokers.
- Will Kafka's access control lists (ACLs) be used? If so, MSK Serverless cannot be selected.
- Is queue semantics a requirement? If you are relying on share groups, as introduced in KIP-932, Express brokers are currently not an option.
- Will Kafka Streams applications run on it? If so, read both the caveat in the Developer Guide and the What's New post, and confirm the specific feature you intend to use.
- Will manual partition reassignment go into the operational procedure? If so, verify the relationship with Intelligent Rebalancing within the target cluster.
- Will you carry dashboards and alarms over from an existing cluster? If so, compare the metrics lists for Standard brokers and Express brokers.
- Which client version is in use? To create new topics with tiered storage, Apache Kafka client version 3.0.0 or later is required. Upgrading the server-side components will not automatically update the client.
13. How It Fails
A design does not break right after the choice. It breaks when it turns out that the premise behind the choice did not match the requirement.| Failure | When Discovered | What Happens |
|---|---|---|
| Production was placed on Standard, while development was on Express. | After a production incident. | The default availability settings are reversed. The development environment has more robust replication and leader election configurations. |
| Express was chosen, assuming tiered storage, when designing retention periods. | During the configuration process. | There is no configuration to separate primary and low-cost tiers. The retention period design needs to be redesigned. |
| Express was tested in development, then Standard was chosen for production. | During the delivery configuration process. | Direct delivery to S3 Tables is not possible. Additional components like Firehose, Flink, or Kafka Connect need to be implemented. |
| Express was chosen while keeping a two-zone subnet design. | At cluster creation. | Creation does not go through. You go back to the subnet design. |
| An Express cluster was created using Kafka 3.6. | Without warning. | Because it has passed its end-of-support date, it may be automatically upgraded to the recommended version at any time. |
| A constraints table for Express was built on what the CDK says. | Late in the implementation. | Three points, the versions, logging, and the instance sizes, differ from what the service does. |
| Planning for 4.x while staying in ZooKeeper mode. | When planning the upgrade. | Upstream 4.0 has no ZooKeeper mode. A migration to KRaft by way of 3.9 has to come first. |
| Attempted to revert to the previous version after migrating to KRaft. | After the migration. | It is not possible to revert. |
| Attempted to revert after disabling tiered storage on a topic. | After disabling tiered storage. | Tiered storage cannot be re-enabled on that topic. |
| Attempted to configure access control lists after migrating to MSK Serverless. | During the access control design phase. | Access control lists are not supported. It needs to be rewritten using IAM. |
14. Frequently Asked Questions
Express brokers and MSK Serverless both remove storage management. What is different between them?
The range of what is not managed. MSK Serverless does not expose the unit called a broker at all, and the service decides both capacity and partition placement. With Express brokers you decide the number and the size of the brokers. The only thing that grows on its own is storage. A cluster with Express brokers is an MSK Provisioned cluster, so you still estimate the broker count.Can existing Standard brokers be migrated to Express brokers?
No. The broker type cannot be switched through the API. You create a new cluster with the broker type you want and move onto it. The means AWS points to is MSK Replicator. Section 8 collects the points that belong in the migration plan.How do you enable tiered storage on Express brokers?
There is no operation that enables it. Tiered storage is a feature of Standard brokers. The storage in Express brokers is a single store with no tier, and the tiering settings themselves do not exist. Both share the property of having virtually no upper limit. The settings you can reach differ.I have read that Express brokers have lower availability. Is that right?
No. The Amazon MSK Developer Guide says the opposite. Express brokers are fixed at a replication factor of 3,min.insync.replicas of 2, and unclean.leader.election.enable of FALSE, and data is always replicated across three Availability Zones. The claim of lower availability may come from the text of the BrokerType enumeration in the AWS CDK. Section 11 records that disagreement.Should you choose KRaft or ZooKeeper?
KRaft, for a new cluster. Apache Kafka 4.0 removed ZooKeeper upstream, and Amazon MSK 3.9.x is the last version that carries both. Clusters built in ZooKeeper mode will either need to be migrated or remain on that version. Migration is irreversible.Can Express brokers run Kafka version 4.1?
No. As of the date this article was checked, the supported versions for Express brokers are 3.6, 3.8, 3.9, and 4.2. 4.0 and 4.1 are not on the list. In the other direction, 4.2 is available on Express brokers only.Can Standard brokers deliver directly to S3 Tables?
No. This delivery is available on Express brokers only. It cannot be used on Standard brokers or on MSK Serverless. Doing the equivalent means standing up Amazon Data Firehose, Managed Service for Apache Flink, or Kafka Connect separately.Can partitions be reassigned by hand on Express brokers?
The sources say different things. The Intelligent Rebalancing page states in its note that it is exclusive with third-party tools, while the Considerations section on the same page also takes in the partition reassignment API. The best practices page for Express brokers is written on the assumption thatkafka-reassign-partitions.sh is used. The operations skill that AWS publishes states that manual reassignment is unavailable while Intelligent Rebalancing is on. Confirm the behavior on the cluster in question before this goes into an operational procedure.Why does this article carry no end-of-support dates for Kafka versions?
Because an already published article holds the table of dates. The Amazon MSK section of the AWS End-of-Support and EOL Reference lists the release date and the end-of-support date for each version. This article only addresses branches that involve design changes.What is wrong with the three deployment modes explanation?
The level of the division. The official structure places two broker types, Standard brokers and Express brokers, inside the MSK Provisioned cluster type, with MSK Serverless standing beside it as a separate cluster type. Treat Express brokers as an option that sits alongside MSK Provisioned and you design without ever checking the quotas and limits of MSK Provisioned.15. Summary
Choosing how to build a cluster in Amazon MSK is choosing the range of work AWS takes over. It is not choosing features. Having work taken over also means letting go of the operations inside that range.Start from the official division. MSK Provisioned holds two broker types, Standard brokers and Express brokers, and MSK Serverless stands beside it as a separate cluster type. It is not a structure of three options in a row. The API has no broker type field, and the type is expressed by the prefix of the instance type.
The storage boundary is what moves the most. On Standard brokers you hold five operations: volume size, tiering, reserving throughput, auto-scaling, and storage capacity alerts. On Express brokers Amazon MSK takes all five over, and the only storage decision left to you is the retention period of a topic. The size and the number of brokers are yours to decide on either broker type.
Tiered storage and Express brokers' built-in storage are distinct concepts. Tiered storage is a feature of Standard brokers, allowing log segments to be moved from a primary tier to a low-cost tier. Express brokers have no tier. What is absent is the concept itself, not a setting that happens to sit at a default.
Choosing Express brokers means that certain operations are no longer available. A two-zone configuration, the T3 and M5 instance families, changes to the replication factor,
min.insync.replicas, and unclean.leader.election.enable, the five storage operations, and the share groups of KIP-932 all fall into that set. Apache Kafka 3.7, 4.0, and 4.1 are not on the list of supported versions for Express brokers.Even when choosing Standard brokers, certain features are unavailable. These include direct delivery to S3 Tables and S3 buckets, Intelligent Rebalancing, operations without maintenance windows, and support for Apache Kafka 4.2.x.
Six choices move in one direction only. They are the broker type, the migration to KRaft, disabling tiered storage on a topic, growing an EBS volume, the Apache Kafka version, and the VPC together with the number of Availability Zones. Changing the broker type means building the cluster again. A migration plan is best started from the list of what will not come across.
The primary sources disagree in ten places. The AWS CDK and the Amazon MSK Developer Guide in particular describe the positioning of Express brokers in exactly opposite terms. Treat the Developer Guide as authoritative for judgments about the specification, and confirm them against the cluster's own API response immediately before you act.
16. References
- Amazon MSK broker types - Amazon Managed Streaming for Apache Kafka
- Amazon MSK Express brokers - Amazon Managed Streaming for Apache Kafka
- Amazon MSK Standard brokers - Amazon Managed Streaming for Apache Kafka
- Storage management for Standard brokers - Amazon Managed Streaming for Apache Kafka
- Tiered storage for Standard brokers - Amazon Managed Streaming for Apache Kafka
- Guidelines for Amazon MSK tiered storage topic-level configuration - Amazon Managed Streaming for Apache Kafka
- Enable tiered storage on an existing Amazon MSK cluster using AWS CLI - Amazon Managed Streaming for Apache Kafka
- Enable and disable tiered storage on an existing Amazon MSK topic - Amazon Managed Streaming for Apache Kafka
- Scale up Amazon MSK Standard broker storage - Amazon Managed Streaming for Apache Kafka
- Provision storage throughput for Standard brokers in a Amazon MSK cluster - Amazon Managed Streaming for Apache Kafka
- Manage storage throughput for Standard brokers in a Amazon MSK cluster - Amazon Managed Streaming for Apache Kafka
- Amazon MSK Provisioned configuration - Amazon Managed Streaming for Apache Kafka
- Express broker configurations - Amazon Managed Streaming for Apache Kafka
- Express brokers read-only configurations - Amazon Managed Streaming for Apache Kafka
- Custom MSK Express broker configurations (Read/Write access) - Amazon Managed Streaming for Apache Kafka
- Metadata management - Amazon Managed Streaming for Apache Kafka
- Migrate from ZooKeeper to KRaft mode - Amazon Managed Streaming for Apache Kafka
- Supported Apache Kafka versions - Amazon Managed Streaming for Apache Kafka
- Amazon MSK version support - Amazon Managed Streaming for Apache Kafka
- Create an MSK Provisioned cluster - Amazon Managed Streaming for Apache Kafka
- Intelligent rebalancing for clusters - Amazon Managed Streaming for Apache Kafka
- Steady state rebalancing for Amazon MSK clusters - Amazon Managed Streaming for Apache Kafka
- Patching on MSK Provisioned clusters - Amazon Managed Streaming for Apache Kafka
- Best practices for Express brokers - Amazon Managed Streaming for Apache Kafka
- What is MSK Serverless? - Amazon Managed Streaming for Apache Kafka
- Configuration properties for MSK Serverless clusters - Amazon Managed Streaming for Apache Kafka
- Amazon MSK quota - Amazon Managed Streaming for Apache Kafka
- Upgrade the Apache Kafka version - Amazon Managed Streaming for Apache Kafka
- Expand the number of brokers in an Amazon MSK cluster - Amazon Managed Streaming for Apache Kafka
- Fault tolerance - AWS Support User Guide
- Amazon MSK metrics for monitoring Standard brokers with CloudWatch - Amazon Managed Streaming for Apache Kafka
- Amazon MSK metrics for monitoring Express brokers with CloudWatch - Amazon Managed Streaming for Apache Kafka
- data delivery for streaming tables to Apache Iceberg - Amazon Managed Streaming for Apache Kafka
- Supported configurations - Amazon Managed Streaming for Apache Kafka
- Streaming tables with Amazon MSK - Amazon Simple Storage Service
- UpdateStorage - Amazon Managed Streaming for Apache Kafka API Reference
- Amazon Managed Streaming for Apache Kafka Construct Library - AWS CDK
- enum BrokerType - AWS CDK
- Managed Apache Kafka Service Features - Amazon MSK Features
- Fully Managed Apache Kafka - Amazon MSK FAQs
- Simplifying Kafka operations with Amazon MSK Express brokers - AWS Big Data Blog
- managing-amazon-msk - Agent Toolkit for AWS
- Express brokers for Amazon MSK is now generally available
- Amazon MSK now supports broker logs on Express Brokers
- Amazon MSK Express Brokers now support automatic topic creation with Kafka Streams
- Amazon MSK Express brokers now deliver data to streaming tables for Apache Iceberg
- Amazon MSK expands Express Brokers to 8 additional AWS Regions
- Amazon MSK Serverless expands to 13 new AWS regions
- Apache Kafka 4.0.0 Release Announcement
- Kafka Streams - Apache Kafka
- KIP-405: Kafka Tiered Storage - Apache Software Foundation
- KIP-932: Queues for Kafka - Apache Software Foundation
- KIP-500: Replace ZooKeeper with a Self-Managed Metadata Quorum - Apache Software Foundation
- AWS Real-Time Streaming Data Pipeline Architecture Guide - Ingestion, Processing, and Delivery with Kinesis, Managed Service for Apache Flink, and OpenSearch
- AWS Messaging and Event Routing Decision Guide - Choosing Between SQS, SNS, EventBridge, and Kinesis
- EventBridge Pipes Event-Driven Architecture Implementation Patterns
- AWS End-of-Support and EOL Reference - Lambda, EKS, RDS and Aurora, ElastiCache, and OpenSearch Service
- AWS History and Timeline regarding Amazon Kinesis - Overview, Functions, Features, Summary of Updates, and Introduction
- AWS Data Lakehouse Architecture Guide - Building a Governed Lakehouse with S3, Lake Formation, Glue, Athena, and Apache Iceberg
- Zero-ETL Integrations on AWS - The Source and Target Matrix Across Amazon Redshift, AWS Glue, and Amazon OpenSearch Service
References:
Tech Blog with curated related content
Written by Hidekazu Konishi